Advanced driver assistance systems are only as good as the data pipelines that train them. For OEMs and Tier-1 suppliers, competitive advantage no longer comes from simply collecting more driving data or deploying automation tools. The real differentiator lies in how automation, annotation tools, and domain expertise are combined to create reliable, high-precision training pipelines for production environments.
As autonomous driving and ADAS capabilities mature, organizations are discovering that data quality, annotation consistency, and scalable AI training operations determine how quickly perception models improve and how safely they perform in real-world scenarios. At scale, ADAS innovation becomes less about algorithms and more about how efficiently sensor data is transformed into accurate, usable training assets.
Also Read: 5 Practical Ways to Improve Data Governance for Financial Institutions
Key Takeaways
Competitive advantage in ADAS now hinges on combining automation with domain-led, precision annotation across synchronized multi-sensor data. Pipelines commonly fail at scale due to multimodal alignment gaps, lapses in pixel/point accuracy, and insufficient coverage of rare, safety-critical scenarios. The winning approach is 3D-first and temporally consistent, leveraging pre-labelling, automated QA, and active learning while concentrating expert review on high-risk scenes. A DTaaS model operationalizes this with measurable quality controls, evolving policies, and tight feedback loops that accelerate production readiness.
Why ADAS Data Pipelines Break at Scale
ADAS perception models depend on dense, multimodal sensor data where even small annotation inaccuracies can create downstream safety risks. A loosely defined bounding box in image annotation or inconsistent 3D object placement can distort distance and velocity estimation, directly affecting braking or collision avoidance decisions.
This challenge escalates because fleets now generate terabytes of sensor data per vehicle per day, sourced from synchronized cameras, LiDAR, and radar systems, each introducing unique sampling behaviors, noise patterns, and failure conditions. Programs must also support multiple sensor generations and regional regulatory requirements simultaneously, increasing pipeline complexity.
As programs scale, a common pattern emerges. Model performance plateaus, labelling teams struggle to keep pace with data volume, and the hidden cost of imprecise data labeling becomes visible only during late validation stages or road testing. For ADAS and Ground Truth leaders, pipeline reliability becomes a bigger constraint than model innovation.
Also Read: Data Governance vs Data Management
Precision Requirements: Where Errors Truly Matter
High-precision ADAS annotation pipelines begin by identifying where mistakes cannot be tolerated. In practice, three precision areas drive most downstream performance issues.
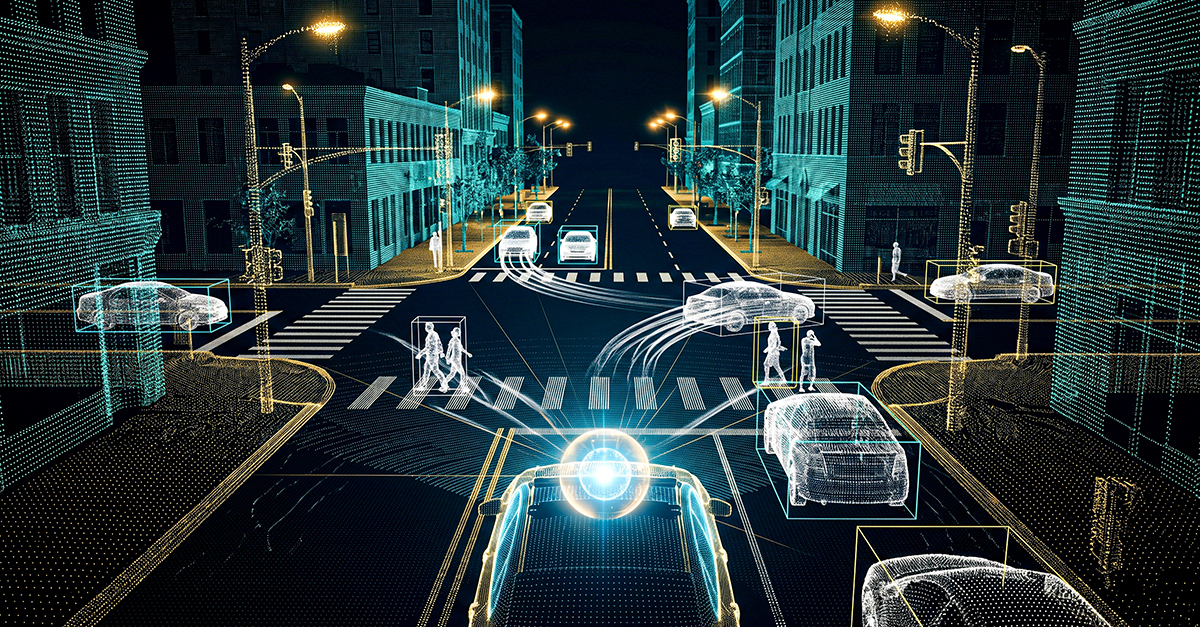
First, pixel- and point-level accuracy is critical. Vehicles, pedestrians, cyclists, and small obstacles require tight and consistent annotations across frames to support reliable detection and tracking. Lane boundaries, curbs, and traffic signage often demand pixel-level image annotation because lateral control algorithms are sensitive to small deviations. Meanwhile, LiDAR cuboids must capture accurate geometry and orientation, requiring annotators who understand spatial depth and occlusions in 3D environments.
Second, environmental complexity increases annotation difficulty. Night driving, rain, fog, snow, glare, and motion blur distort sensor perception, making objects partially hidden or ambiguous. Maintaining annotation consistency across these conditions is essential for ADAS models that must generalize globally.
Third, safety-critical edge cases carry disproportionate importance. Emergency vehicles in unusual positions, construction diversions, unexpected pedestrian behavior, fallen cargo, or animals on highways occur infrequently but dominate safety validation reviews. Pipelines trained primarily on clean highway data often fail in these situations unless rare scenarios are deliberately curated and annotated.
When precision or consistency weakens in any of these areas, perception performance degrades even if overall accuracy metrics appear acceptable.
Multi-Sensor Complexity: Why Generic Workflows Fall Short
Modern ADAS systems depend on synchronized multi-sensor inputs, not isolated camera feeds. Cameras, LiDAR, and radar must be aligned, annotated, and validated as a unified perception system.
Generic annotation workflows struggle because they typically operate frame by frame or sensor by sensor. Production pipelines instead require synchronized temporal alignment, 3D-first labelling workflows that project consistently into 2D views, and temporal consistency so object identities remain stable across sequences. They must also incorporate intelligent sampling strategies to handle enormous sensor data volumes without overwhelming annotation teams.
Without domain-aware workflows, inconsistent labels appear between modalities and frames, leading to brittle sensor fusion and tracking systems that perform well in controlled tests but struggle in real-world autonomous driving scenarios.
Also Read: How To Use Consumer Digital Footprints to Personalize Services
Automation Is Necessary, But Not Sufficient
Automation is essential to manage ADAS data volumes, yet automation alone cannot guarantee safety-grade quality. The most successful pipelines use semi-automated data annotation algorithms for ADAS and automated driving to process large volumes while domain experts ensure correctness.
Pre-labelling models can automatically generate initial annotations, allowing annotators to focus on corrections and edge cases. Depending on scenario complexity, this approach can reduce manual effort by up to 80 percent, shifting human effort toward refining difficult scenes and correcting misclassifications.
Automated quality checks further strengthen pipelines by identifying ontology violations, missing classes, or inconsistencies between annotators. Confidence scoring and inter-annotator agreement measures help surface uncertain segments that need expert review.
Active learning workflows further optimize data labelling by identifying samples where models are uncertain, enabling annotators to focus on high-impact data rather than redundant frames. This loop accelerates AI training efficiency while reducing overall annotation cost.
The true benefit of automation is not just efficiency gains but the ability to concentrate domain expertise on safety-critical scenarios.
Where Domain Expertise Changes Outcomes
Automation accelerates pipelines. Domain expertise ensures they remain safe and reliable.
Annotation teams that understand automotive safety requirements and sensor characteristics deliver measurable improvements. Ontology design grounded in safety requirements ensures labels map directly to perception and planning decisions. Scenario-aware policies adapt annotation practices to geography, weather, and regulatory differences. Experts also curate rare edge cases, ensuring they are fully annotated and reused across validation and training cycles.
Tight feedback loops between ADAS engineering teams and annotation teams allow failures to be traced quickly to data issues, enabling rapid policy updates and pipeline improvements.
In a Data Training as a Service model, automation, processes, and domain talent are delivered as an integrated managed capability rather than isolated tooling investments.
Questions Decision Makers Should Be Asking
As ADAS programs expand, leaders increasingly evaluate pipelines not only for throughput but for strategic resilience. Decision makers must assess whether annotation quality is measurable and predictable, whether costs scale linearly with data volume, and whether rare scenarios are systematically captured and reused. They must also ask whether labelling policies evolve alongside model failures and whether pipelines can support both current engineering needs and future AI-driven training systems.
Pipelines today must serve not only human engineers but also AI agents and simulation systems that rely on structured, high-quality data. Organizations that treat data pipelines as long-term infrastructure rather than operational overhead are better positioned to accelerate autonomous driving innovation.
A DTaaS Approach to High-Precision ADAS Pipelines
For OEMs and automotive research teams, the challenge is no longer deciding between internal or outsourced annotation. The real priority is establishing predictable pipelines that consistently deliver training-ready datasets.
A DTaaS approach focuses on measurable improvements in model readiness rather than annotation throughput alone. Mature pipelines integrate multimodal ingestion tailored to sensor stacks, hybrid automation workflows combined with expert review, domain-trained annotation teams aligned with safety checkpoints, and continuous feedback loops linking model performance to labelling policies.
For Heads of Data, ADAS, and AI training teams, this translates into faster perception model improvement, stronger edge-case coverage, and clearer visibility into how data investments influence on-road safety performance.
As ADAS data complexity continues to grow, pipelines that successfully combine automation, annotation expertise, and domain intelligence will define the next generation of production-grade autonomous systems.