Auto manufacturers and Tier 1 suppliers in India, Europe, and the UK have spent years chasing ever-larger datasets to power ADAS technology and safety-critical models. Sensors flood R&D teams with petabytes, but this volume obsession hides a brutal truth: poor data quality drives up costs—including ADAS calibration cost and ADAS recalibration expenses—delays deployments, and risks safety certifications. In 2025, as self-driving crashes tripled and regulations tightened, forward-thinking Heads of Data, ADAS, and R&D are flipping the script—prioritizing curated ground truth over raw accumulation in advanced driver assistance systems.
The Industry Obsession with “More Data”
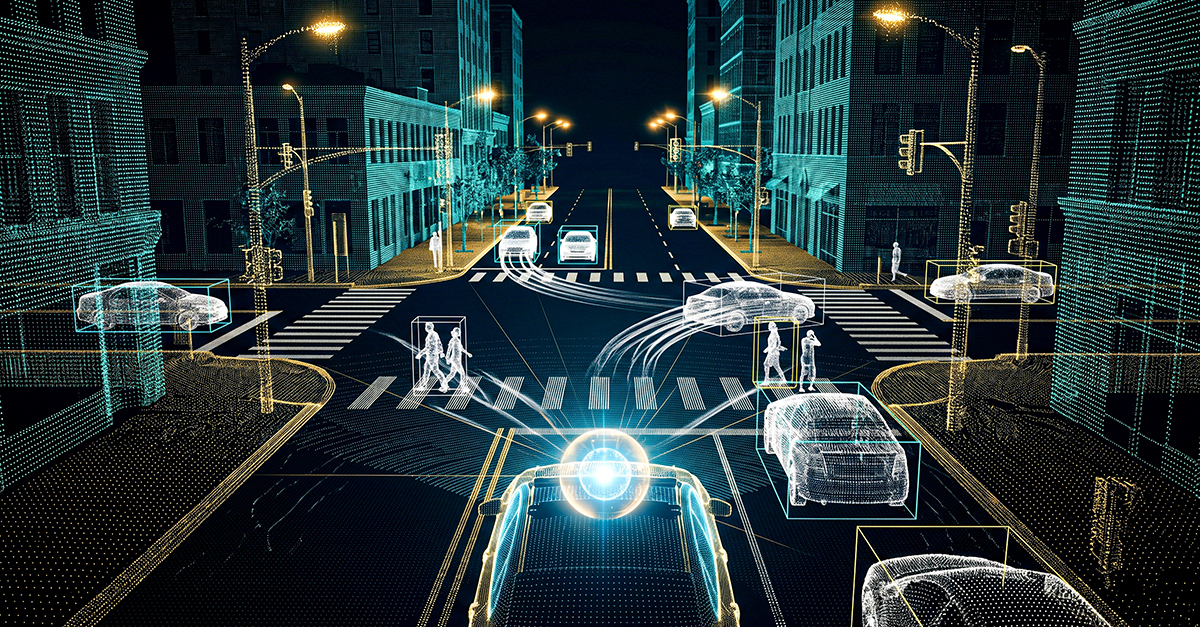
The ADAS sensor market exploded to $36 billion in 2025, driven by multi-modal fusion from cameras, LiDAR, radar, and ultrasonics central to ADAS. Every Level 3+ system demands massive inputs: a single autonomous vehicle generates 4TB of data per day across 12+ cameras alone, powering features like adaptive cruise control. OEMs like those in Europe’s premium segment and India’s rising EV makers turned data volume into the default KPI. Why? Early perception models scaled linearly with samples—more miles driven equaled better generalization for what is ADAS calibration processes and beyond.
But 2025 exposed the cracks. Self-driving incidents tripled amid edge-case failures, from foggy UK motorways to monsoon-drenched Indian highways. Brute-force collection from fleet telematics and test tracks overwhelmed video labeling teams. Vendors promised “millions of annotated frames,” yet models faltered on long-tail scenarios like erratic pedestrians or occluded cyclists—complicating ADAS calibration. The KPI that built the industry now breaks it, as storage, compute, and human data labeling costs spiral without proportional gains in autonomous driving.
Also Read: Data Governance vs Data Management
Where the Real Cost Is Hiding
Nobody talks about the shadow expenses of junk data, including inflated ADAS recalibration needs. Poorly curated raw feeds inflate labeling efforts by 40-60%: blurry frames, misaligned sensors, or redundant highway loops force annotators to waste hours on low-value pixels during data labeling. A Head of Video Labeling in Pune might ship 100,000 images weekly, only for downstream QA to reject 30% due to inconsistent bounding boxes or missing occlusions, spiking ADAS calibration cost.
Inconsistent ontologies compound this. One European vendor tags “pedestrian” broadly, while an Indian partner splits into “adult/juvenile/crossing.” Merging datasets creates Frankenstein training sets, where models learn noise instead of signals. Signal-to-noise ratios plummet below 20% in multi-vendor pipelines, triggering endless retraining cycles and ADAS recalibration. Each iteration burns GPU hours $10,000+ per run on H100 clusters and delays milestones by weeks.
Rework hits hardest. Low-quality inputs cascade: bad labels yield weak models, forcing data training teams to loop back for “just a few more edge cases.” A Director of Central Research in Munich reported 25% of their annual data budget vanishing into fixes, not innovation. For India-Europe collaborations, timezone gaps and cultural labeling variances amplify these pains, turning operational data labeling tasks into strategic bottlenecks for ADAS technology.
Why Safety-Critical Systems Feel the Pain First
Advanced driver assistance and functional safety under ISO 26262 tolerate zero ambiguity. Noisy labels don’t just degrade accuracy—they risk ASIL-D violations, where a single mislabeled rare event (think child darting from a driveway during adaptive cruise control) could cascade to recalls or lawsuits. Medical imaging parallels this: one fuzzy MRI annotation derails diagnostics; in ADAS, it endangers lives and demands precise what is ADAS calibration.
Edge cases dominate here. Long-tail conditions—less than 1% of data but 80% of failures—amplify quality gaps, especially with LiDAR inputs. Nighttime deer crossings in rural Europe or pothole-dodging rickshaws in Mumbai appear rarely, so poor curation starves models of signal, inflating ADAS calibration needs. 2025 regulatory pressures from the EU AI Act, India’s Bharat NCAP, and UK’s Automated Vehicles Act demand auditable ground truth. Validation engineers spend months proving dataset integrity, delaying OTA updates by quarters.
Heads of Functional Safety know this intimately: certification bodies scrutinize every label for bias, drift, and completeness in autonomous driving. Raw volume offers no defense when a model’s confidence drops 15% on underrepresented scenarios. Safety-first teams in auto ancillary firms feel it acutely—supplier contracts hinge on defect-free data training handoffs.
Also Read: How To Use Consumer Digital Footprints to Personalize Services
Data Quality as a Force Multiplier
High-quality ground truth doesn’t just fix errors; it multiplies efficiency. Curated datasets slash data training cycles from 10 to 4 epochs, as models converge faster on clean signals for ADAS. Time-to-validation drops 30-50%: fewer false positives mean streamlined ISO 26262 flows and quicker sign-off from safety officers, minimizing ADAS recalibration.
Consider model confidence. “Training-ready” data—pre-filtered for scenarios, ontology-aligned, and QA-vetted—boosts F1 scores by 12-18% on perception benchmarks, including adaptive cruise control. Compute savings compound: one OEM cut inference costs 25% by pruning noisy samples early. For Heads of Data Training, this shifts budgets from ops to innovation, like fine-tuning on proprietary long-tail captures with precise data labeling.
Performance lifts extend to deployment. Robust models handle real-world drift better, reducing OTA patches post-launch. In cost terms, quality delivers 3x ROI: $1 invested in curation saves $3 in rework, video labeling, and delays—directly impacting ADAS calibration cost. Apexon’s pipelines embed this multiplier, turning data from cost center to accelerator for advanced driver assistance.
What Leading Teams Are Doing Differently
Progressive auto leaders ditch brute-force for precision in ADAS technology. They start with smarter selection: active learning algorithms score raw data for informativeness, prioritizing edge cases over volume. A Tech Lead in AI/ML might query, “Which 10% of my 1M-frame fleet dump covers unseen monsoons?”—pulling high-entropy samples first for efficient data training.
Ontology discipline rules. Centralized schemas enforce consistency across India-based video labeling farms and European R&D hubs. Tools map vendor-specific tags to a master hierarchy, catching drifts in real-time. Scenario-led curation follows: teams bucket data by use cases (e.g., “urban intersection left-turn”) before data labeling, ensuring coverage maps to deployment risks like ADAS calibration.
Also Read: 3 Steps to Build an AI Foundation
Early QA integration flips the script. Instead of end-of-pipeline scrubs, automated checks flag inconsistencies mid-flow—pixel-level drift detection, label consensus scoring, even physics-based plausibility (e.g., “car velocity mismatches LiDAR”). A Head of Pre-Labeling in Chennai integrates this via API hooks, reducing downstream rejects by 50%. Chiefs of Ground Truth Data Products layer in domain expertise: safety engineers co-annotate rare events, baking compliance from day one for autonomous driving.
Road Safety Project Groups in the UK lead here, partnering with firms like Apexon for hybrid human-AI loops. Results? 40% faster iterations, 25% cost drops, and models hitting 99% recall on tails—streamlining what is ADAS calibration.
The Shift the Industry Must Make
The pivot demands treating data training as a strategic capability, not an operational chore. Accumulate less, convert more: build data engines that transform raw sensors into model fuel via continuous refinement for ADAS. Directors of Strategic Sourcing rethink vendor RFPs—not “cheapest frames per hour,” but “ontology-aligned, QA-scored throughput” with low ADAS recalibration risk.
In India, this means scaling data labeling with AI pre-labeling, overseen by Euro-spec quality gates. Europe demands traceability for GDPR audits; UK focuses on post-Brexit standards. Chief Product Managers weave this into roadmaps: data pipelines as IP, monetized via reusable ground truth marketplaces supporting advanced driver assistance.
Apexon operationalizes this shift. Our ADAS data platforms—deployed for Tier 1s across continents—feature scenario simulators, federated ontologies, and ML-driven QA. We cut your hidden costs—including ADAS calibration cost—while future-proofing against regs. Heads of Analytics see dashboards tracking quality KPIs in real-time, from signal ratios to tail coverage.
Closing Thought: Train on the Right Data
The future of ADAS technology and safety models won’t reward who collects the most data, but who masters the right data. As 2026 ramps regulatory scrutiny and compute wars, quality-first teams pull ahead—fewer recalls, faster certifications, superior margins in autonomous driving.
Ready to audit your pipelines? Apexon’s experts deliver bespoke data training strategies for auto leaders in India, Europe, and the UK. Contact us today to uncover your hidden costs and unlock quality-driven velocity.